Saturday, 20 April 2024

AWS Cloud Practitioner — Top 100 Must-Know key Points (CLF-C02)

136 – 210: Compute, Storage, Database, Analytics, AI

  1. EC2 Instance Families – General (t), Compute (c), Memory (r/x), Storage (i), GPU (g/p).
  2. EC2 Instance Types Naming – Example: m5.large → m = family, 5 = generation, large = size.
  3. Spot Fleet – Group of spot instances for cost optimization.
  4. Placement Groups – Cluster, Partition, Spread (HPC & big workloads).
  5. Amazon Fargate – Serverless containers; no EC2 management.
  6. ECS (Elastic Container Service) – Container orchestration (AWS-native, cheaper).
  7. EKS (Elastic Kubernetes Service) – Managed Kubernetes (heavy workloads).
  8. ECS Anywhere – Run ECS on on-prem or hybrid.
  9. Firecracker MicroVM – Technology behind Lambda & Fargate.
  10. Lambda Layers – Share common code/resources across Lambda functions.
  11. Lambda Provisioned Concurrency – Zero cold start.
  12. Lambda Execution Role – Permissions function needs to access AWS resources.
  13. Lambda Function Timeout – Max 15 minutes.
  14. AWS Batch Compute Environments – Automate batch workloads on EC2/Spot/Fargate.
  15. Amazon Lightsail Containers – Simple container hosting.
  16. Spot Blocks – Spot instances with guaranteed run time.
  17. AMI (Amazon Machine Image) – Blueprint for EC2 instances.
  18. Elastic GPU – Attach GPU to EC2.
  19. EC2 Hibernate – Preserves RAM to EBS.
  20. ENI (Elastic Network Interface) – Multiple IPs, network cards.
  21. EC2 Instance Metadata v2 – IMDSv2 more secure (mandatory in exam).
  22. Instance Store – Temporary storage, data lost on stop/terminate.
  23. Capacity Reservations – Guarantee EC2 capacity for a period.
  24. EC2 Dedicated Host – Physical server fully dedicated to you.
  25. EC2 Dedicated Instance – Runs on hardware not shared with other accounts.
  26. S3 Access Points – Custom access paths for apps.
  27. S3 Inventory – Report of objects & metadata.
  28. S3 Object ACLs – Legacy permissions (discouraged, but exam asks).
  29. S3 Block Public Access – Account-level public block.
  30. S3 Bucket Policy – JSON resource-based permission.
  31. S3 CORS – Cross-domain access configuration.
  32. S3 Select – Query a subset of S3 object.
  33. S3 Multi-Part Upload – Recommended for >100MB objects.
  34. S3 Transfer Acceleration – Speeds uploads using CloudFront edge locations.
  35. S3 Intelligent-Tiering – Automatically moves objects for cost saving.
  36. S3 Requester Pays – Requester pays for download.
  37. EFS Throughput Modes – Bursting, Provisioned.
  38. EFS Storage Classes – Standard, Infrequent Access (IA).
  39. EBS Volume Types – gp3, io2, sc1, st1.
  40. EBS Multi-Attach – Attach to multiple EC2 at the same time.
  41. EBS Snapshots Archive – Cheaper archival storage.
  42. EBS Fast Snapshot Restore – High-performance restore.
  43. AWS Storage Gateway Types – File, Volume, Tape.
  44. AWS Snowball Edge Compute – Includes GPU, compute power.
  45. AWS DataSync – Automated large-scale data transfer.
  46. AWS Transfer Family – Managed SFTP/FTP/FTPS.
  47. AWS Backup Policies – Backup plans, vaults, schedules.
  48. Glacier Retrieval Classes – Expedited, Standard, Bulk.
  49. S3 Lifecycle Policies – Automate class transitions + deletion.
  50. AWS EFS One-Zone – Cheaper but less durable.
  51. RDS Multi-AZ Failover – Automatic standby failover.
  52. RDS Read Replicas – Read scaling.
  53. RDS Automated Backups – Point-in-time recovery.
  54. Aurora Global Database – Lag < 1 second between regions.
  55. DynamoDB Global Tables – Multi-region active-active.
  56. DynamoDB TTL – Automatic expiry of items.
  57. DynamoDB Streams – Change data capture for Lambda.
  58. DynamoDB Accelerator (DAX) – In-memory cache for Dynamo.
  59. ElastiCache Redis – Sub-millisecond caching.
  60. OpenSearch Dashboards – Visualization tool (Kibana alternative).
  61. Athena Federated Query – Query other sources beyond S3.
  62. Glue Crawlers – Scan data & generate schema.
  63. Glue Jobs – ETL pipelines.
  64. Kinesis Analytics – Real-time SQL analytics on streaming data.
  65. Kinesis Shards – Unit of capacity for streams.
  66. Redshift Concurrency Scaling – Handles spike workloads.
  67. Redshift RA3 Nodes – Managed storage.
  68. EMR Serverless – No cluster management.
  69. EMR Notebooks – Data exploration with Jupyter.
  70. SageMaker Ground Truth – Labeling tool for ML data.
  71. SageMaker Studio – IDE for ML model lifecycle.
  72. Transcribe – Speech-to-text.
  73. Translate – Language translation.
  74. Comprehend – NLP sentiment analysis.
  75. Forecast – Time-series forecasting using ML.

🔥 SET-9 (25 Points) – Developer Tools, DevOps, Monitoring, Cost, Support

  1. CloudFormation Drift Detection – Checks differences between stack & deployed resources.
  2. CloudFormation Change Sets – Preview changes before applying.
  3. CDK (Cloud Development Kit) – Define infra using Python/TS/Java.
  4. Elastic Beanstalk Health Monitoring – Green / Yellow / Red indicators.
  5. AWS SAM CLI – Test Lambda / APIs locally.
  6. CodeStar – Unified DevOps project setup.
  7. CodeArtifact – Package dependency management (npm / pypi / maven).
  8. CodeGuru Reviewer – AI code review.
  9. CodeGuru Profiler – Detects performance bottlenecks.
  10. CloudWatch Events – Deprecated → EventBridge.
  11. CloudWatch Logs Insights – Query logs using SQL-like syntax.
  12. CloudWatch Metrics Resolution – Standard: 1 min | High-resolution: 1–30 sec.
  13. CloudWatch Embedded Metric Format – Send custom metrics.
  14. CloudTrail Insights – Detect unusual API activity.
  15. AWS Health API – Programmatic health alerts.
  16. AWS Service Quotas – Manage & request service limit increases.
  17. Cost Categories – Group cost data logically.
  18. Reservation Utilization Report – See how RIs are used.
  19. Savings Plans Utilization – Commitment utilization tracking.
  20. AWS Marketplace Metering – Pay-as-you-go software usage.
  21. AWS Concierge Support – Enterprise-only cost help.
  22. TAM (Technical Account Manager) – Enterprise support engineer.
  23. AWS Abuse Team – Report spam / misuse.
  24. AWS Penetration Testing Rules – Allow list for pentesting EC2.
  25. Well-Architected Tool – Checks workloads against AWS 5 pillars.

Tuesday, 13 February 2024

AWS Cloud Practitioner — Top 76 Must-Know Points (CLF-C02)

236 – 260: Edge, Networking & Hybrid

  1. Edge Locations Count – CloudFront POPs worldwide (exam sometimes asks conceptually).
  2. Regional Edge Caches – Bigger caches between origin and POP.
  3. AWS Local Zones – Compute closer to users in metro cities.
  4. Wavelength Zones – For 5G ultra-low latency edge compute.
  5. AWS Outposts Rack – Smaller on-prem AWS hardware.
  6. AWS Outposts Server – Even smaller, fits in standard IT rack.
  7. AWS Egress Fees – Cost for data leaving AWS.
  8. Public vs Elastic IP – Elastic IP → fixed, account-owned.
  9. ENA (Elastic Network Adapter) – High-performance networking for EC2.
  10. Global Accelerator vs CloudFront – GA → TCP/UDP app acceleration | CF → content delivery & caching.
  11. VPC Flow Logs – Capture network traffic metadata.
  12. VPC Reachability Analyzer – Find connectivity issues.
  13. IPv6 in VPC – Dual-stack possible.
  14. AWS Shield Standard – Free DDoS protection.
  15. AWS Route 53 Health Checks – Monitor endpoints & failover.
  16. Route 53 Routing Policies – Simple, Weighted, Latency, Geolocation, Failover, Multi-value.
  17. AWS IoT Fleet Hub – Monitor IoT devices fleet-wide.
  18. AWS IoT Device Defender – Security audits for IoT devices.
  19. AWS IoT Device Management – Scale registration + remote actions.
  20. AWS RoboMaker – Robotics simulation & deployment.
  21. Direct Connect Gateway – Connect DC to multiple VPCs across regions.
  22. Transit Gateway Multicast – Support multicast traffic.
  23. Cloud WAN – Global wide-area networking managed by AWS.
  24. PrivateLink – Private access to services via interface endpoints.
  25. Hybrid DNS with Route 53 Resolver – On-prem ↔ AWS DNS integration.

🔥 SET-11 (25 Points) – Data, AI, Application Integration, Messaging

  1. Kinesis Enhanced Fan-Out – 1 MB/s per shard throughput for consumers.
  2. Kinesis Extended Retention – Store streams up to 1 year.
  3. Kinesis Shard Splitting – Increase capacity.
  4. Kinesis Shard Merging – Reduce capacity.
  5. SQS Delay Queue – Delay messages up to 15 min.
  6. SQS Long Polling – Reduces empty responses → lowers cost.
  7. SQS FIFO Throughput – Per-message ordering guaranteed.
  8. SNS Mobile Push – Push to APNS / FCM.
  9. SNS SMS Types – Promotional vs Transactional.
  10. EventBridge Pipes – Point-to-point event flow.
  11. EventBridge Schedule – Cron-based serverless jobs.
  12. Step Functions Express Workflow – High-throughput rapid workflows.
  13. Glue DataBrew – Visual data preparation without coding.
  14. Glue Elastic Views – Unified view of multiple data stores.
  15. Lake Formation – Data lake permission control.
  16. Redshift Spectrum Pricing – Pay only per scanned TB.
  17. Redshift Materialized Views – Precomputed data for performance.
  18. OpenSearch UltraWarm Storage – Warm storage tier.
  19. OpenSearch Domain – Cluster of search nodes.
  20. Forecast Use-Cases – Retail sales, cloud capacity, traffic prediction.
  21. Personalize – Recommendation engine.
  22. Lookout for Metrics – Detect anomalies using ML.
  23. Lookout for Equipment – Predict equipment failures.
  24. Textract Queries – Search for specific fields in documents.
  25. Rekognition Custom Labels – Train custom image models.
  26. Transcribe Call Analytics – Contact-center call analysis.
  27. Polly Neural TTS – More natural speech.
  28. Amazon Lex V2 – Chatbot building (NLP + intent slots).
  29. Amazon Bedrock – Foundation models for GenAI (conceptual).
  30. AWS HealthLake – Healthcare data processing (HIPAA-ready).

Monday, 10 April 2023

Defragmentation Implementation in ODI

Defragmentation Implementation in ODI:

Execute below Code in database to create tables:

create table bi11g_dw.defragment_table as

select owner, table_name,sum(BLOCKS) S,'N' as flag

FROM ALL_TABLES

where owner in ('BI11G_DW', 'BI12C_BIA_ODIREPO','STG') and

(ROUND(((BLOCKS*16/1024)-(NUM_ROWS*AVG_ROW_LEN/1024/1024)),2)/ROUND(((BLOCKS*16/1024)),2))*100 >20 and

--table_name not like '%CFG%' and avg_row_len <> '0' group by owner, table_name order by s ASC;

------------------------------------------------------------------------------------------------------------

create table bi11g_dw.defragment_ind_table as select a.owner, a.table_name, b.index_name, 'N' as FLAG from bi11g_dw.defragment_table a, all_indexes b where a.table_name=b.table_name and a.owner=b.owner;

-----------------------------------------------------------------------------------------

 CREATE TABLE "BI11G_DW"."DEFRAGMENT_TMP" 

   ( "TABLE_NAME" VARCHAR2(50 BYTE)

   )

------------------------------------------------------------------------------------------

ODI Proc code:

-------------------

step 1:

update bi11g_dw.defragment_table  set flag='N';

Step2:

DECLARE

    CUR1 SYS_REFCURSOR;

    CUR2 SYS_REFCURSOR;

    V_TABLENAME VARCHAR2(50);

    V_INDEXNAME VARCHAR2(50);

    V_OWNER VARCHAR2(50);

    BEGIN

      OPEN CUR1 FOR

        select owner,table_name from bi11g_dw.defragment_table WHERE FLAG='N' order by s ASC;

      LOOP

        FETCH CUR1 INTO V_OWNER,V_TABLENAME;

        EXIT WHEN CUR1%NOTFOUND;

        EXECUTE IMMEDIATE'TRUNCATE TABLE bi11g_dw.defragment_tmp';

        insert into  bi11g_dw.defragment_tmp values (V_TABLENAME);

      EXECUTE IMMEDIATE 'ALTER TABLE '||V_OWNER||'.'||V_TABLENAME||' MOVE';

          OPEN CUR2 FOR SELECT OWNER,TABLE_NAME, INDEX_NAME FROM bi11g_dw.defragment_ind_table WHERE TABLE_NAME = V_TABLENAME;

          LOOP

            FETCH CUR2 INTO V_OWNER,V_TABLENAME,V_INDEXNAME;

            EXIT WHEN CUR2%NOTFOUND;

            EXECUTE IMMEDIATE'TRUNCATE TABLE bi11g_dw.defragment_tmp';

        insert into  bi11g_dw.defragment_tmp values (V_TABLENAME);

             EXECUTE IMMEDIATE 'ALTER INDEX '||V_OWNER||'.'||V_INDEXNAME||' REBUILD ONLINE';

             UPDATE bi11g_dw.defragment_ind_table SET FLAG='Y' WHERE TABLE_NAME=V_TABLENAME AND INDEX_NAME=V_INDEXNAME;

             commit;

            END LOOP;

         dbms_stats.gather_table_stats(ownname => V_OWNER, tabname =>V_TABLENAME, estimate_percent =>DBMS_STATS.AUTO_SAMPLE_SIZE, method_opt => 'FOR ALL COLUMNS SIZE AUTO');

      UPDATE bi11g_dw.defragment_table SET FLAG='Y' WHERE TABLE_NAME=V_TABLENAME;

      COMMIT;

       END LOOP;

       END;


ODI Proc2:

---------

update Bi11G_DW.defragment_table set flag='E' where table_name in (select * from Bi11G_DW.defragment_tmp)

How to check table space in database

 Query : To check tablespace in database 

select t.tablespace,  t.totalspace as " Totalspace(MB)",
     round((t.totalspace-nvl(fs.freespace,0)),2) as "Used Space(MB)",
     nvl(fs.freespace,0) as "Freespace(MB)",
     round(((t.totalspace-nvl(fs.freespace,0))/t.totalspace)*100,2) as "%Used",
     round((nvl(fs.freespace,0)/t.totalspace)*100,2) as "% Free",
     us.USERNAME
     from
     (select round(sum(d.bytes)/(1024*1024)) as totalspace,d.tablespace_name tablespace
     from dba_data_files d
     group by d.tablespace_name) t,
     (select round(sum(f.bytes)/(1024*1024)) as freespace,f.tablespace_name tablespace
     from dba_free_space f
     group by f.tablespace_name) fs,
     (  SELECT USERNAME ,default_tablespace FROM  dba_users)  us     where t.tablespace=fs.tablespace (+)   AND t.tablespace(+) = us.default_tablespace
     order by "% Free";

Saturday, 28 May 2022

Get results for all tables row count in schema and truncate all tables at a time in schema

get results for all tables row count in schema

---------------------------------------------------

SET SERVEROUTPUT ON;

DECLARE 

VAL NUMBER;

BEGIN

for i in (SELECT table_name FROM all_tables WHERE owner = 'Ora_Schema' and table_name like '%GL%')

LOOP

EXECUTE IMMEDIATE 'SELECT count(*) from Ora_Schema.' || i.table_name INTO VAL;

DBMS_OUTPUT.PUT_LINE(i.table_name || ' | ' || VAL);

END LOOP;

END;


truncate all tables at a time in schema

---------------------------------------------------


set serveroutput on;

begin

for t1 in (SELECT table_name FROM all_tables WHERE owner = 'Orc_schema' and table_name in ('GL_LEDGERS','GL_CALENDARS')) loop

    begin

       ----- dbms_output.put_line('truncate table '||t1.table_name || ';');    

        execute immediate ('truncate table '||t1.table_name);

    end;

end loop;

end;


Monday, 25 April 2022

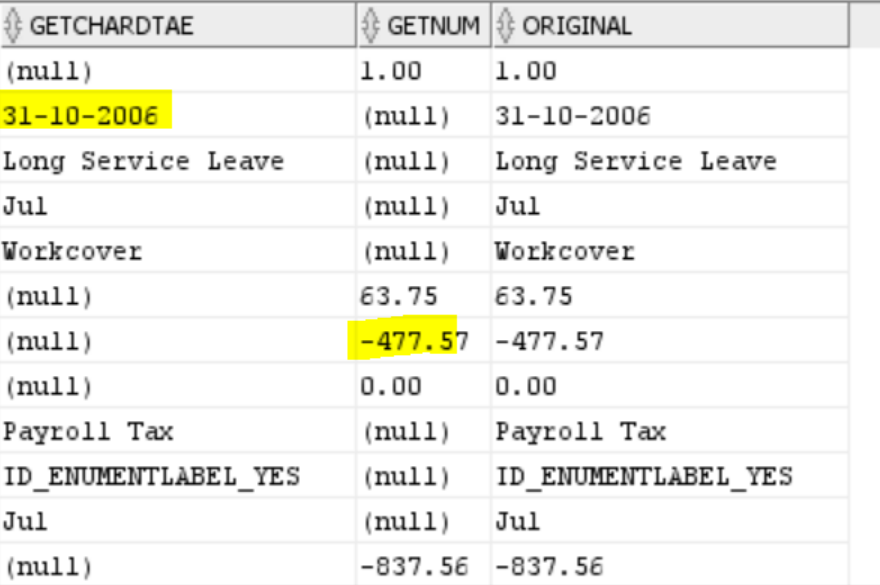
get/extract char , date , numeric values from varchar column

requirement:

amount column having numeric data , char data and date also

So char /date data into one column and numeric (+ve, -ve ) values in another column

use below query to acheive that:

select

case when  trim(TRANSLATE(replace(substr(amount_in_char,0,1),'-','')||substr(amount_in_char,2), '0123456789,.', ' ')) is not null 

then amount_in_char end getchardtae,

case  when trim(TRANSLATE(replace(substr(amount_in_char,0,1),'-','')||substr(amount_in_char,2), '0123456789,.', ' ')) is  null 

then amount_in_char end getnum,

amount_in_char original from w_plan_fs; 


Tuesday, 19 April 2022

Find out the long running queries/locked objects in database

 Use below queries

check the odi session id status in database


Example:

 select * from GV$SESSION WHERE ACTION LIKE '%21622%'; (odi session id)

SELECT * FROM V$SESSION_LONGOPS WHERE SID=1392;

SELECT * FROM V$SESSION WHERE SEQ#='9383';ACTION LIKE '%21622%';

SELECT SQL_FULLTEXT ,LOCKED_TOTAL,SQL_ID FROM GV$SQL WHERE SQL_ID='383g771j';

SELECT * FROM GV$SQL;

alter system kill session '648,51886' IMMEDIATE

select username, status from v$session where SID=12;

Friday, 11 March 2022

employee-manager relationship hierarchy using SQL Query


As you can see, I had to put a hardcoded value for EMPLEVEL field in the Recursive section of the query above. This was because I did not join the Recursive section of the query with our recursive CTE. Now, in order to make the entire hierarchical query work with actual hierarchical level of records assigned, we need to complete the INNER JOIN as in the below query. Notice the difference in value of EMPLEVEL field. This is the complete hierarchical query in CTE format. Please note that ORDER BY is optional here.

WITH OURCTE (EMPNO, ENAME, MGR, EMPLEVEL)
AS (SELECT EMPNO, ENAME, MGR, 1 EMPLEVEL ---Initial Subquery
FROM Emp
WHERE MGR IS NULL
UNION ALL
SELECT E.EMPNO, E.ENAME, E.MGR, CTE.EMPLEVEL + 1 ---Recursive Subquery
FROM EMP E
INNER JOIN OURCTE CTE ON E.MGR = CTE.EMPNO –Inner Join
WHERE E.MGR IS NOT NULL)
SELECT *
FROM OURCTE
ORDER BY EMPLEVEL;

If you need to display the manager name next to the manager ID, refer to the following query:

SELECT CTE.EMPNO, CTE.ENAME, CTE.MGR, E.ENAME “MGR NAME”, CTE.EMPLEVEL
FROM (
WITH OURCTE (EMPNO, ENAME, MGR, EMPLEVEL)
AS (SELECT EMPNO, ENAME, MGR, 1 EMPLEVEL –Initial Subquery
FROM Emp
WHERE MGR IS NULL
UNION ALL
SELECT E.EMPNO, E.ENAME, E.MGR, CTE.EMPLEVEL + 1 –Recursive Subquery
FROM EMP E
INNER JOIN OURCTE CTE ON E.MGR = CTE.EMPNO
WHERE E.MGR IS NOT NULL)
SELECT *
FROM OURCTE
ORDER BY EMPLEVEL) CTE
LEFT OUTER JOIN EMP E ON CTE.MGR = E.EMPNO
ORDER BY CTE.EMPLEVEL,E.ENAME; 

Thursday, 9 December 2021

BICC PVO job issues in ODI 12c


#ERROR1:

Caused By: javax.script.ScriptException: javax.script.ScriptException: java.lang.InterruptedException: sleep interrupted


Solution:

BICC extract script failing in the timespane

Go to mapping and select LKM LKM BICC ADW Extrernal table-- BICC job timeout- 4000 or 1000 or 0


#ERROR2:

ODI-1228: Task Merge rows-IKM Oracle Merge-Load TGT_FSCMTOPMODELAM_FINVRMRRSHAREDPUBLICMODELAM_PERFOBLIGATIONLINDISTSPVO_1 fails on the target connection .

Caused By: java.sql.SQLException: ORA-30926: unable to get a stable set of rows in the source tables


Solution:

use ikm oracle incremental update merge instead of ikm oracle merge

Check primary key enabled in mapping .

If same data trying to insert /update on target table  which is already exist in target table then it will not allow to update or insert using merge

delete data from target or source based on requirement

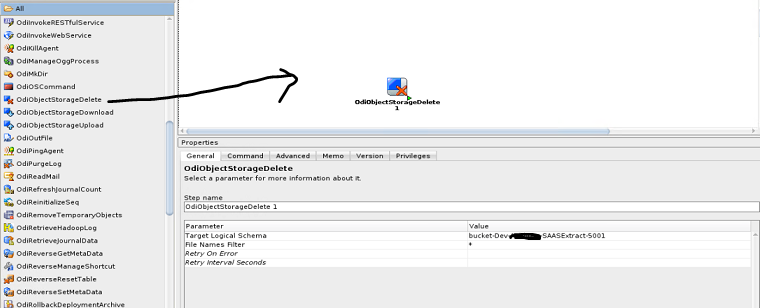
Delete files from object storage in odi package

 Delete files from object storage using odi object


configure oracle object storage technology in topology 

create package

drag the OdiObjectStorageDelete object

add details for target logical schema, filter file names 

save and execute


End-to-End Databricks S3 Workflow: Connect, Create Tables, Archive, and Move Files

End-to-End Databricks S3 Workflow: Connect, Create Tables, Archive, and Move Files Introduction An end-to-end Databricks S3 pipeline ofte...